


2025 VCEPrep Linux Foundation CKAD Dumps and Exam Test Engine
Linux Foundation CKAD DUMPS WITH REAL EXAM QUESTIONS
NEW QUESTION # 10
Context
Task:
1) Create a secret named app-secret in the default namespace containing the following single key-value pair:
Key3: value1
2) Create a Pod named ngnix secret in the default namespace.Specify a single container using the nginx:stable image.
Add an environment variable named BEST_VARIABLE consuming the value of the secret key3.
Answer:
Explanation:
Solution:


NEW QUESTION # 11
Refer to Exhibit.
Set Configuration Context:
[student@node-1] $ | kubectl
Config use-context k8s
Context
A web application requires a specific version of redis to be used as a cache.
Task
Create a pod with the following characteristics, and leave it running when complete:
* The pod must run in the web namespace.
The namespace has already been created
* The name of the pod should be cache
* Use the Ifccncf/redis image with the 3.2 tag
* Expose port 6379
Answer:
Explanation:
Solution:
NEW QUESTION # 12
Context
Task
Create a new deployment for running.nginx with the following parameters;
* Run the deployment in the kdpd00201 namespace. The namespace has already been created
* Name the deployment frontend and configure with 4 replicas
* Configure the pod with a container image of lfccncf/nginx:1.13.7
* Set an environment variable of NGINX__PORT=8080 and also expose that port for the container above
Answer:
Explanation:
Solution:


NEW QUESTION # 13
Context
Task:
A Dockerfile has been prepared at -/human-stork/build/Dockerfile
1) Using the prepared Dockerfile, build a container image with the name macque and lag 3.0. You may install and use the tool of your choice.
2) Using the tool of your choice export the built container image in OC-format and store it at -/human stork/macque 3.0 tar
Answer:
Explanation:
Solution:
NEW QUESTION # 14
Context
Context
You are tasked to create a ConfigMap and consume the ConfigMap in a pod using a volume mount.
Task
Please complete the following:
* Create a ConfigMap named another-config containing the key/value pair: key4/value3
* start a pod named nginx-configmap containing a single container using the nginx image, and mount the key you just created into the pod under directory /also/a/path
Answer:
Explanation:
Solution:


NEW QUESTION # 15
Exhibit:
Context
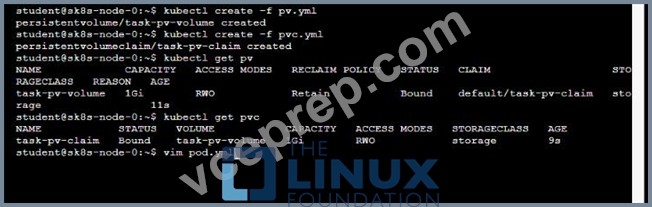
A project that you are working on has a requirement for persistent data to be available.
Task
To facilitate this, perform the following tasks:
* Create a file on node sk8s-node-0 at /opt/KDSP00101/data/index.html with the content Acct=Finance
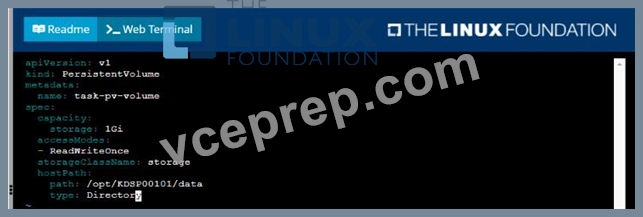
* Create a PersistentVolume named task-pv-volume using hostPath and allocate 1Gi to it, specifying that the volume is at /opt/KDSP00101/data on the cluster's node. The configuration should specify the access mode of ReadWriteOnce . It should define the StorageClass name exam for the PersistentVolume , which will be used to bind PersistentVolumeClaim requests to this PersistenetVolume.
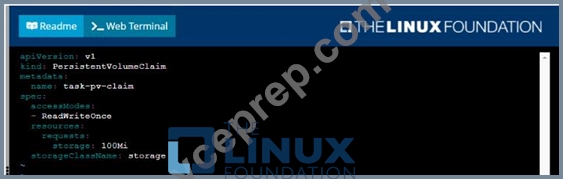
* Create a PefsissentVolumeClaim named task-pv-claim that requests a volume of at least 100Mi and specifies an access mode of ReadWriteOnce
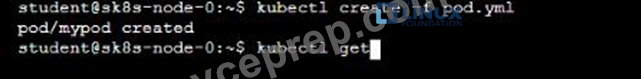
* Create a pod that uses the PersistentVolmeClaim as a volume with a label app: my-storage-app mounting the resulting volume to a mountPath /usr/share/nginx/html inside the pod

- A. Solution:





- B. Solution:
Answer: A
NEW QUESTION # 16 
Context
A pod is running on the cluster but it is not responding.
Task
The desired behavior is to have Kubemetes restart the pod when an endpoint returns an HTTP 500 on the
/healthz endpoint. The service, probe-pod, should never send traffic to the pod while it is failing. Please complete the following:
* The application has an endpoint, /started, that will indicate if it can accept traffic by returning an HTTP 200.
If the endpoint returns an HTTP 500, the application has not yet finished initialization.
* The application has another endpoint /healthz that will indicate if the application is still working as expected by returning an HTTP 200. If the endpoint returns an HTTP 500 the application is no longer responsive.
* Configure the probe-pod pod provided to use these endpoints
* The probes should use port 8080
Answer:
Explanation:
See the solution below.
Explanation
Solution:
apiVersion: v1
kind: Pod
metadata:
labels:
test: liveness
name: liveness-exec
spec:
containers:
- name: liveness
image: k8s.gcr.io/busybox
args:
- /bin/sh
- -c
- touch /tmp/healthy; sleep 30; rm -rf /tmp/healthy; sleep 600
livenessProbe:
exec:
command:
- cat
- /tmp/healthy
initialDelaySeconds: 5
periodSeconds: 5
In the configuration file, you can see that the Pod has a single Container. The periodSeconds field specifies that the kubelet should perform a liveness probe every 5 seconds. The initialDelaySeconds field tells the kubelet that it should wait 5 seconds before performing the first probe. To perform a probe, the kubelet executes the command cat /tmp/healthy in the target container. If the command succeeds, it returns 0, and the kubelet considers the container to be alive and healthy. If the command returns a non-zero value, the kubelet kills the container and restarts it.
When the container starts, it executes this command:
/bin/sh -c "touch /tmp/healthy; sleep 30; rm -rf /tmp/healthy; sleep 600" For the first 30 seconds of the container's life, there is a /tmp/healthy file. So during the first 30 seconds, the command cat /tmp/healthy returns a success code. After 30 seconds, cat /tmp/healthy returns a failure code.
Create the Pod:
kubectl apply -f https://k8s.io/examples/pods/probe/exec-liveness.yaml
Within 30 seconds, view the Pod events:
kubectl describe pod liveness-exec
The output indicates that no liveness probes have failed yet:
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
24s 24s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image
"k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id
86849c15382e; Security:[seccomp=unconfined]
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id
86849c15382e
After 35 seconds, view the Pod events again:
kubectl describe pod liveness-exec
At the bottom of the output, there are messages indicating that the liveness probes have failed, and the containers have been killed and recreated.
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
37s 37s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image
"k8s.gcr.io/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id
86849c15382e; Security:[seccomp=unconfined]
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id
86849c15382e
2s 2s 1 {kubelet worker0} spec.containers{liveness} Warning Unhealthy Liveness probe failed: cat: can't open
'/tmp/healthy': No such file or directory
Wait another 30 seconds, and verify that the container has been restarted:
kubectl get pod liveness-exec
The output shows that RESTARTS has been incremented:
NAME READY STATUS RESTARTS AGE
liveness-exec 1/1 Running 1 1m
NEW QUESTION # 17
Refer to Exhibit.
Context
As a Kubernetes application developer you will often find yourself needing to update a running application.
Task
Please complete the following:
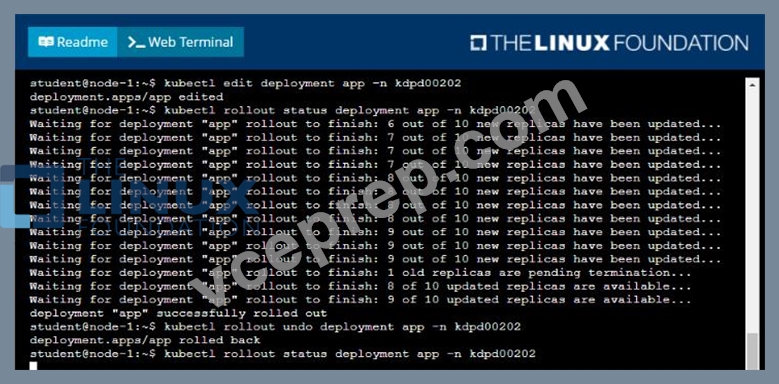
* Update the app deployment in the kdpd00202 namespace with a maxSurge of 5% and a maxUnavailable of 2%
* Perform a rolling update of the web1 deployment, changing the Ifccncf/ngmx image version to 1.13
* Roll back the app deployment to the previous version
Answer:
Explanation:
Solution: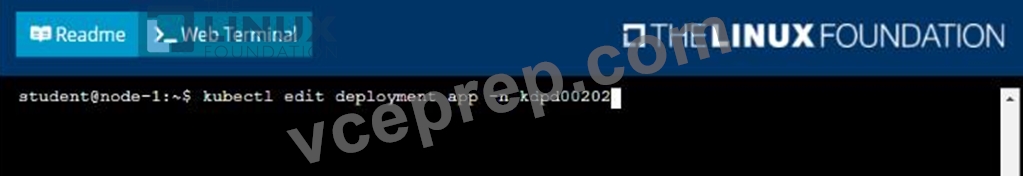


NEW QUESTION # 18
Context
Context
A project that you are working on has a requirement for persistent data to be available.
Task
To facilitate this, perform the following tasks:
* Create a file on node sk8s-node-0 at /opt/KDSP00101/data/index.html with the content Acct=Finance
* Create a PersistentVolume named task-pv-volume using hostPath and allocate 1Gi to it, specifying that the volume is at /opt/KDSP00101/data on the cluster's node. The configuration should specify the access mode of ReadWriteOnce . It should define the StorageClass name exam for the PersistentVolume , which will be used to bind PersistentVolumeClaim requests to this PersistenetVolume.
* Create a PefsissentVolumeClaim named task-pv-claim that requests a volume of at least 100Mi and specifies an access mode of ReadWriteOnce
* Create a pod that uses the PersistentVolmeClaim as a volume with a label app: my-storage-app mounting the resulting volume to a mountPath /usr/share/nginx/html inside the pod
Answer:
Explanation:
Solution:
NEW QUESTION # 19
Context
Task:
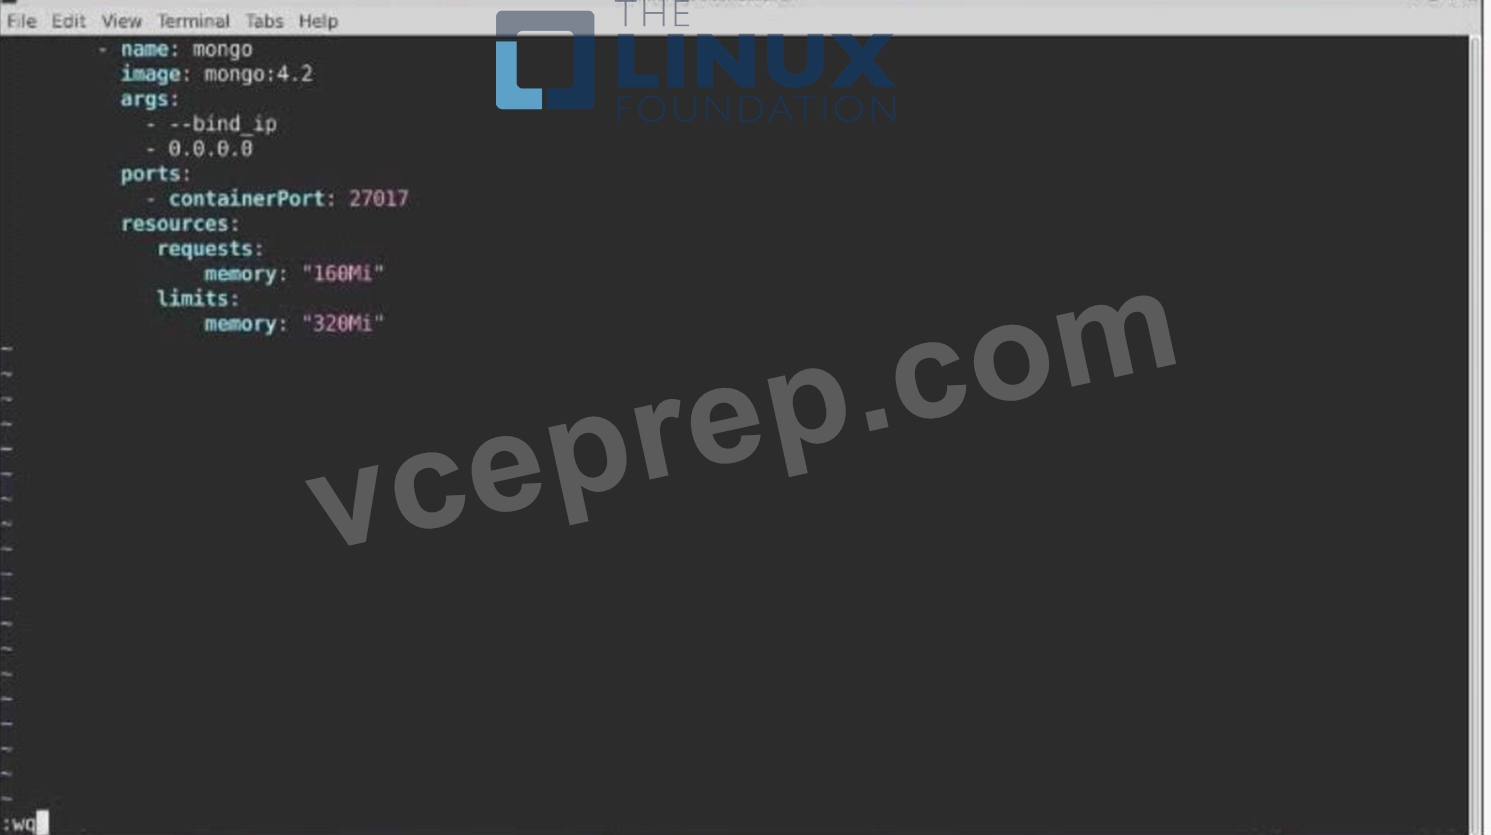
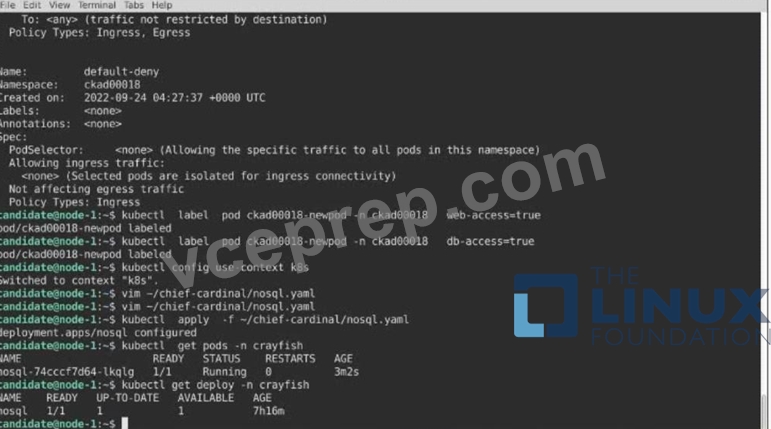
The pod for the Deployment named nosql in the craytisn namespace fails to start because its container runs out of resources.
Update the nosol Deployment so that the Pod:
1) Request 160M of memory for its Container
2) Limits the memory to half the maximum memory constraint set for the crayfah name space.
Answer:
Explanation:
Solution:

NEW QUESTION # 20
Exhibit:
Context
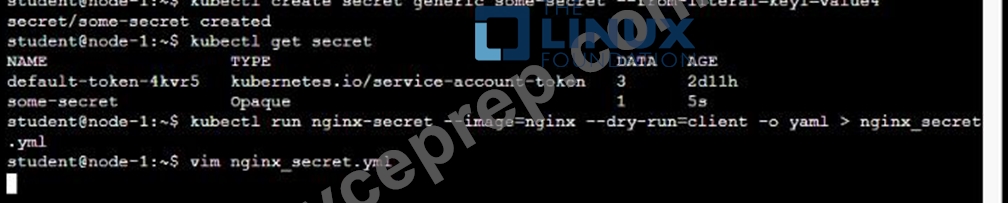
You are tasked to create a secret and consume the secret in a pod using environment variables as follow:
Task
* Create a secret named another-secret with a key/value pair; key1/value4
* Start an nginx pod named nginx-secret using container image nginx, and add an environment variable exposing the value of the secret key key 1, using COOL_VARIABLE as the name for the environment variable inside the pod
- A. Solution:


- B. Solution:

Answer: B
NEW QUESTION # 21
Exhibit:
Context
A pod is running on the cluster but it is not responding.
Task
The desired behavior is to have Kubemetes restart the pod when an endpoint returns an HTTP 500 on the /healthz endpoint. The service, probe-pod, should never send traffic to the pod while it is failing. Please complete the following:
* The application has an endpoint, /started, that will indicate if it can accept traffic by returning an HTTP 200. If the endpoint returns an HTTP 500, the application has not yet finished initialization.
* The application has another endpoint /healthz that will indicate if the application is still working as expected by returning an HTTP 200. If the endpoint returns an HTTP 500 the application is no longer responsive.
* Configure the probe-pod pod provided to use these endpoints
* The probes should use port 8080
- A. Solution:

In the configuration file, you can see that the Pod has a single Container. The periodSeconds field specifies that the kubelet should perform a liveness probe every 5 seconds. The initialDelaySeconds field tells the kubelet that it should wait 5 seconds before performing the first probe. To perform a probe, the kubelet executes the command cat /tmp/healthy in the target container. If the command succeeds, it returns 0, and the kubelet considers the container to be alive and healthy. If the command returns a non-zero value, the kubelet kills the container and restarts it.
When the container starts, it executes this command:
/bin/sh -c "touch /tmp/healthy; sleep 30; rm -rf /tmp/healthy; sleep 600"
For the first 30 seconds of the container's life, there is a /tmp/healthy file. So during the first 30 seconds, the command cat /tmp/healthy returns a success code. After 30 seconds, cat /tmp/healthy returns a failure code.
Create the Pod:
kubectl apply -f https://k8s.io/examples/pods/probe/exec-liveness.yaml
Within 30 seconds, view the Pod events:
kubectl describe pod liveness-exec
The output indicates that no liveness probes have failed yet:
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
24s 24s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image "k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id 86849c15382e; Security:[seccomp=unconfined]
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id 86849c15382e
After 35 seconds, view the Pod events again:
kubectl describe pod liveness-exec
At the bottom of the output, there are messages indicating that the liveness probes have failed, and the containers have been killed and recreated.
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
37s 37s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully
2s 2s 1 {kubelet worker0} spec.containers{liveness} Warning Unhealthy Liveness probe failed: cat: can't open '/tmp/healthy': No such file or directory
Wait another 30 seconds, and verify that the container has been restarted:
kubectl get pod liveness-exec
The output shows that RESTARTS has been incremented:
NAME READY STATUS RESTARTS AGE
liveness-exec 1/1 Running 1 1m - B. Solution:
In the configuration file, you can see that the Pod has a single Container. The periodSeconds field specifies that the kubelet should perform a liveness probe every 5 seconds. The initialDelaySeconds field tells the kubelet that it should wait 5 seconds before performing the first probe. To perform a probe, the kubelet executes the command cat /tmp/healthy in the target container. If the command succeeds, it returns 0, and the kubelet considers the container to be alive and healthy. If the command returns a non-zero value, the kubelet kills the container and restarts it.
When the container starts, it executes this command:
/bin/sh -c "touch /tmp/healthy; sleep 30; rm -rf /tmp/healthy; sleep 600"
For the first 30 seconds of the container's life, there is a /tmp/healthy file. So during the first 30 seconds, the command cat /tmp/healthy returns a success code. After 30 seconds, cat /tmp/healthy returns a failure code.
Create the Pod:
kubectl apply -f https://k8s.io/examples/pods/probe/exec-liveness.yaml
Within 30 seconds, view the Pod events:
kubectl describe pod liveness-exec
The output indicates that no liveness probes have failed yet:
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
24s 24s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image "k8s.gcr.io/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id 86849c15382e; Security:[seccomp=unconfined]
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id 86849c15382e
After 35 seconds, view the Pod events again:
kubectl describe pod liveness-exec
At the bottom of the output, there are messages indicating that the liveness probes have failed, and the containers have been killed and recreated.
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
37s 37s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image "k8s.gcr.io/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image "k8s.gcr.io/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id 86849c15382e; Security:[seccomp=unconfined]
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id 86849c15382e
2s 2s 1 {kubelet worker0} spec.containers{liveness} Warning Unhealthy Liveness probe failed: cat: can't open '/tmp/healthy': No such file or directory
Wait another 30 seconds, and verify that the container has been restarted:
kubectl get pod liveness-exec
The output shows that RESTARTS has been incremented:
NAME READY STATUS RESTARTS AGE
liveness-exec 1/1 Running 1 1m
Answer: B
NEW QUESTION # 22 
Task
You have rolled out a new pod to your infrastructure and now you need to allow it to communicate with the web and storage pods but nothing else. Given the running pod kdsn00201 -newpod edit it to use a network policy that will allow it to send and receive traffic only to and from the web and storage pods.

Answer:
Explanation:
See the solution below.
Explanation
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
name: internal-policy
namespace: default
spec:
podSelector:
matchLabels:
name: internal
policyTypes:
- Egress
- Ingress
ingress:
- {}
egress:
- to:
- podSelector:
matchLabels:
name: mysql
ports:
- protocol: TCP
port: 3306
- to:
- podSelector:
matchLabels:
name: payroll
ports:
- protocol: TCP
port: 8080
- ports:
- port: 53
protocol: UDP
- port: 53
protocol: TCP
NEW QUESTION # 23
Context
Task
A Deployment named backend-deployment in namespace staging runs a web application on port 8081.
Answer:
Explanation:
Solution:


NEW QUESTION # 24
Context
Task:
A pod within the Deployment named buffale-deployment and in namespace gorilla is logging errors.
1) Look at the logs identify errors messages.
Find errors, including User "system:serviceaccount:gorilla:default" cannot list resource "deployment" [...] in the namespace "gorilla"
2) Update the Deployment buffalo-deployment to resolve the errors in the logs of the Pod.
The buffalo-deployment 'S manifest can be found at -/prompt/escargot/buffalo-deployment.yaml
Answer:
Explanation:
Solution:
NEW QUESTION # 25
Refer to Exhibit.
Task:
1) Create a secret named app-secret in the default namespace containing the following single key-value pair:
Key3: value1
2) Create a Pod named ngnix secret in the default namespace.Specify a single container using the nginx:stable image.
Add an environment variable named BEST_VARIABLE consuming the value of the secret key3.
Answer:
Explanation:
Solution:


NEW QUESTION # 26
......
2025 New VCEPrep CKAD PDF Recently Updated Questions: https://www.vceprep.com/CKAD-latest-vce-prep.html
CKAD Exam with Guarantee Updated 33 Questions: https://drive.google.com/open?id=1A7VwjwHI8VG34Mat7pYawsmg7D2FT_DK